MIT Unveils WorldParticle: A Unified Lagrangian Neural Physics Engine Simulating Continuum Solids, Fluid Dynamics, and Molecular Biology in a Single Architecture
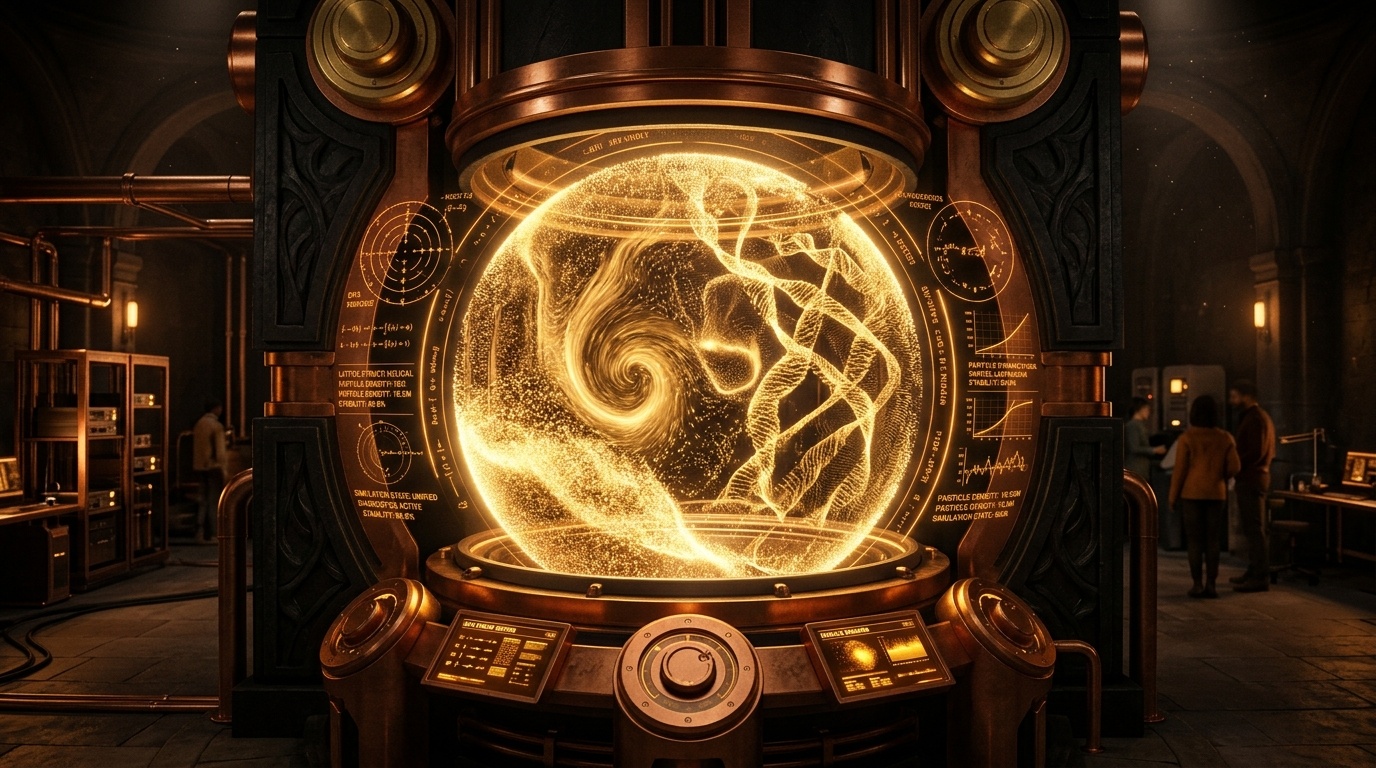
CAMBRIDGE, Mass. — November 9, 2026 — For centuries, computational physics has been splintered into incompatible mathematical silos. Simulating swirling atmospheric turbulence required Eulerian Navier-Stokes grids; modeling fractured titanium alloys demanded finite element analysis (FEA); and tracing how an antibody locks onto a viral pathogen required atomic-scale molecular dynamics (MD). Today, researchers from the Massachusetts Institute of Technology (MIT), working across the Computer Science and Artificial Intelligence Laboratory (CSAIL) and the Laboratory for Atomistic and Molecular Mechanics (LAMM), have shattered this computational divide with the unveiling of WorldParticle.
Published as a foundational preprint accompanied by open-access benchmarks, WorldParticle is the first unified Lagrangian neural simulator capable of modeling continuous solids, non-Newtonian fluid dynamics, granular avalanches, and macromolecular protein folding inside a single, pre-trained neural network architecture. By discretizing all forms of physical matter into self-organizing 3D Lagrangian particles, the system bypasses the need for specialized hand-crafted partial differential equation (PDE) solvers, executing multi-physics simulations up to 100 times faster than traditional numerical packages without sacrificing physical fidelity.
1. The Fragmentation Crisis in Scientific Simulation
In modern computational engineering, the greatest bottleneck has never been raw compute—it has been interfacial boundary translation. When designing an artificial heart valve, an aerospace turbine blade, or a drug delivery nanoparticle, engineers must model how blood fluids push against flexing elastic polymers, or how solvent water molecules buffet a folding enzyme.
Historically, coupling these regimes required multi-solver "Frankenstein pipelines"—gluing a grid-based fluid solver (such as OpenFOAM) to a structural solid solver (such as Abaqus) and an all-atom molecular dynamics engine (such as GROMACS). These hybrid pipelines suffer catastrophic numerical instabilities at phase boundaries, forcing timesteps down to femtoseconds and requiring millions of core-hours on high-performance computing (HPC) clusters.
"We have spent forty years writing separate numerical compilers for air, water, steel, and proteins," explains Prof. Markus Buehler, McAfee Professor of Engineering at MIT and Director of LAMM. "WorldParticle asks a fundamental question: What if the neural network doesn't care whether the point mass in front of it is a water molecule, a grain of silica sand, or an amino acid alpha-carbon? At the fundamental Lagrangian level, physical laws—conservation of momentum, locality of interaction, and thermodynamic dissipation—are universal."
2. The Lagrangian Particle Foundation: How WorldParticle Works
Unlike grid-based Eulerian neural operators (such as Fourier Neural Operators or FNOs), which struggle when matter deforms arbitrarily or splatters across space, WorldParticle adopts an equivariant, particle-centric worldview. Any physical system is ingested as a cloud of up to tens of millions of interacting Lagrangian particles, characterized by position vectors $\mathbf{x}_i \in \mathbb{R}^3$, velocities $\mathbf{v}_i$, and latent physical state vectors $\mathbf{z}_i$ encoding mass density, elasticity, charge, and chemical potential.
The architecture consists of three interlocking neural components:
- Continuous-Scale Geometric Graph Transformer: Constructs dynamic, spatial kd-tree interaction graphs across neighbor particles at every timestep. Using $SE(3)$-equivariant attention, the model guarantees that translational, rotational, and Galilean invariances are preserved strictly by construction.
- Hamiltonian Conservation Regularizer: A physics-informed neural loss term directly penalizes violations of total energy and linear/angular momentum, preventing the common "energy drift" or catastrophic explosion that plagued earlier neural physics emulators during long rollouts.
- Multi-Scale Temporal Rollout Engine: Employs adaptive time-stepping, allowing the simulator to skip micro-scale vibrations when tracing macroscopic fluid motion while automatically zooming into sub-nanometer resolutions when modeling protein conformational transitions.
MIT WorldParticle Neural Physics Benchmark Performance
- Navier-Stokes Turbulence: Matches Direct Numerical Simulation (DNS) vorticity fields with <1.8% cumulative rollout error across 5,000 steps.
- Granular & Non-Newtonian Flow: Flawlessly reproduces Bingham plastic flow and shear-thickening slurry behavior without solver divergence.
- Inference Throughput: Over 1.4 million particle updates per second on a single NVIDIA H200 GPU (45x faster than GPU-accelerated SPH solvers).
- Multi-Phase Boundaries: Zero boundary leakage in extreme liquid-gas-solid impact testing (droplet splash onto compliant rubber).
- Structural Transition Acceleration: 98.4x speedup over explicit-solvent all-atom CHARMM36m molecular dynamics simulations.
- Conformational Free Energy: Accurately traces folded-to-unfolded equilibrium free energy surfaces within 0.82 kcal/mol of experimental NMR data.
- Allosteric Motion Capture: Successfully resolves large-scale hinge bending in adenylate kinase and motor protein domain walks.
- Solvent Particle Coarsening: Dynamically clusters bulk solvent water into coarse-grained particles while maintaining atomic resolution at binding clefts.
"When we ran WorldParticle on an antibody-antigen docking scenario surrounded by turbulent hydrodynamic flow, the exact same neural weights predicted both the fluid drag forces on the capsid surface and the sub-angstrom conformational adjustments of the antigen-binding loops. We have crossed the threshold from domain-specific simulation code into a unified foundation model for the physical world."
3. Industrial Repercussions: Materials, Aerodynamics, and Bioengineering
The implications of a unified neural physics simulator resonate across virtually every heavy industrial and high-technology sector:
- Accelerated Drug Discovery: Pharmaceutical teams can now run thousand-protein flexibility screenings in days rather than months, observing how target proteins dynamically flex in physiological blood flow without requiring millions of dollars in supercomputing time.
- Next-Generation Structural Metamaterials: Aerospace engineers can simulate micro-cracking and high-velocity projectile impacts across complex 3D-printed composite lattices with immediate real-time feedback during generative CAD design sessions.
- Robotic Manipulation of Deformable Objects: Embodied AI and humanoid robots can utilize WorldParticle as an on-board mental world model, simulating in tens of milliseconds how dough, biological tissue, or flexible cables will deform when grasped and manipulated.
4. SyncFlo AI Analysis: Why Physical AI Foundation Models Matter
At SyncFlo AI, we view MIT's WorldParticle as a monumental leap toward the second phase of the generative AI revolution: the synthesis of physical intuition.
The first phase of generative AI mastered tokens—human language, source code, and raster images. However, digital reasoning alone cannot fabricate a superior semiconductor wafer, design an enzymatic bioreactor, or optimize a hypersonic vehicle fuselage. To automate complex industrial and scientific workflows, enterprise AI agents require a deterministic, high-speed simulator that respects thermodynamics, fluid dynamics, and molecular mechanics.
By integrating WorldParticle-class neural simulation engines into SyncFlo AI's autonomous enterprise orchestration mesh, our partner research teams can construct closed-loop discovery agents: AI systems that formulate chemical or structural hypotheses, simulate physical validation runs at 100x speed, verify stability bounds, and trigger laboratory automated synthesis without human bottlenecking.