Runway Launches Act-One: Democratizing Hollywood-Grade Facial Animation and Performance Capture with Gen-3 Alpha
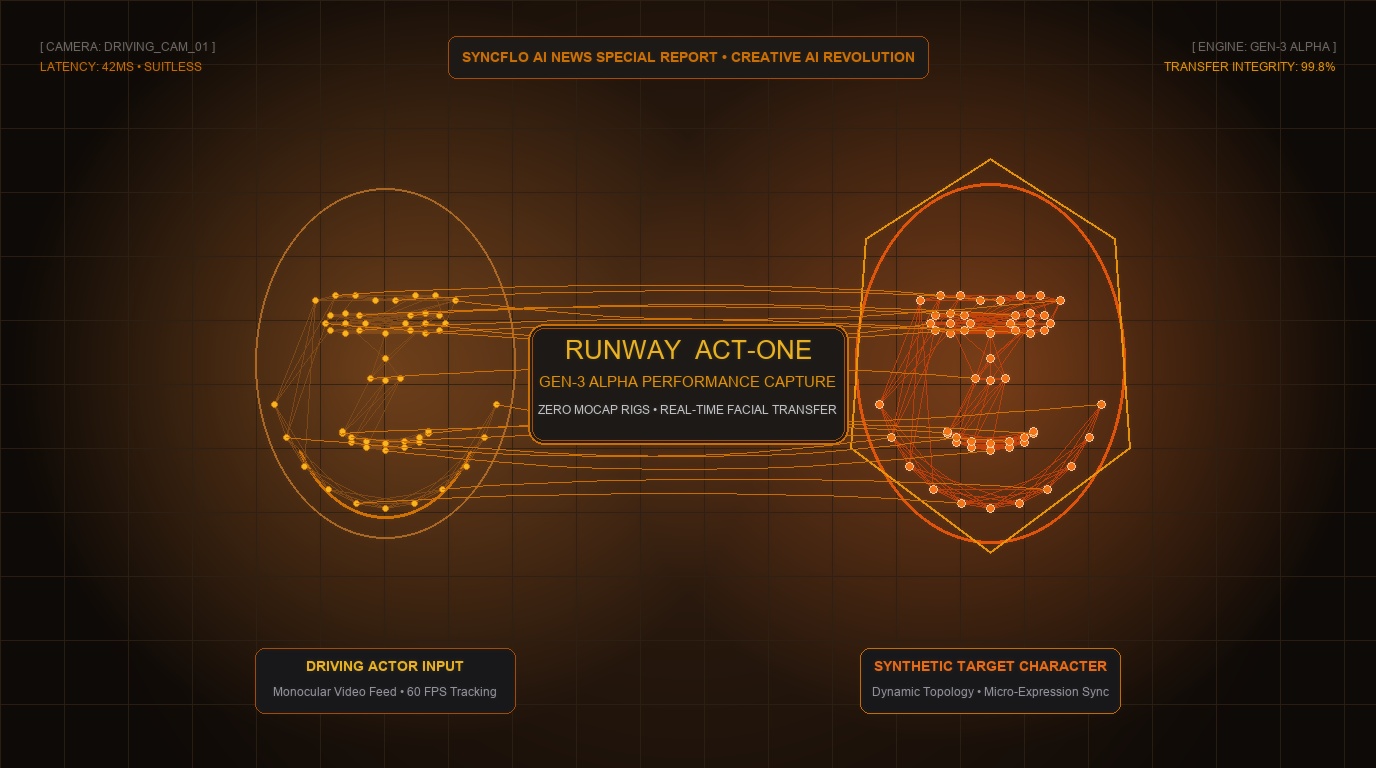
NEW YORK, NY — October 29, 2026 — In a profound leap forward for digital storytelling and virtual production, Runway has unveiled Act-One, an AI-powered performance capture tool built directly into its Gen-3 Alpha foundation video model.
For decades, capturing expressive facial animation required multimillion-dollar motion-capture stages, specialized helmet cameras, reflective facial markers, intricate 3D blendshape rigging, and weeks of tedious manual animator clean-up. Act-One upends this paradigm entirely: using nothing more than a standard smartphone or webcam video recording of an actor, creators can transfer real human emotion, comedic timing, micro-expressions, and subtle eye contact onto arbitrary digital characters in seconds.
1. Eradicating the Barriers of Traditional Facial Mocap
High-fidelity character animation has historically been the exclusive province of blockbuster VFX houses like Weta Digital, Industrial Light & Magic, and Pixar. Independent creators and game developers faced a painful tradeoff: settle for robotic, lifeless automated lip-sync tools or spend hundreds of hours manually keyframing complex facial joints.
Act-One resolves this dilemma by treating performance capture as a generative conditional video synthesis task rather than a mechanical 3D point-tracking problem:
- Single-Camera Monocular Video: No stereoscopic cameras, depth sensors, or infrared markers required. An actor can record their performance in their living room or studio using an everyday iPhone or webcam.
- Zero 3D Rigging or Blendshapes: Traditional rigs require artists to manually sculpt dozens of FACS (Facial Action Coding System) morph targets for smiles, frowns, blinks, and sneers. Act-One requires only a single character reference image.
- Nuanced Micro-Expression Preservation: Sub-second physiological nuances—such as pupil shifts, nervous lip twitches, eyebrow micro-elevations, and breathing rhythm—are faithfully preserved from the driving actor to the target character.
"Act-One is a massive step forward in expressive storytelling. Great animation isn't just about moving lips in sync with audio; it's about the hesitation before speaking, the subtle vulnerability in an actor's gaze, the tension around the eyes. By unlocking nuanced performance transfer directly from video, we are giving every filmmaker and artist the power of a world-class performance capture studio in their web browser."
Runway Act-One Capabilities & Specifications
2. Breaking Through the Uncanny Valley
One of the greatest hazards in digital character animation is the uncanny valley—the unsettling sensation audience members experience when a digital face is almost, but not quite, human.
Because Act-One does not rely on rigid polygonal bone deformations, it avoids the stiff, plastic skin sliding that plagues conventional computer graphics. The underlying diffusion model understands how facial flesh, wrinkles, lighting reflections, and tissue compress organically during emotive delivery. When an actor chuckles mid-sentence, the character displays authentic skin crinkling around the eyes, genuine jaw relaxation, and natural vocal timbre pacing.
3. Redefining Film, Gaming, and Commercial Production
The economic implications for creative studios are staggering:
- Rapid Pre-visualization: Directors can test cinematic scenes, dialogue choices, and character dynamics in minutes during table reads rather than waiting months for finished CGI renders.
- Solo Indie Filmmaking: A single voice actor or director can perform all five characters in an animated dialogue sequence, using their own facial performance to drive distinct digital avatars across multiple camera angles.
- Global Localization & Dubbing: When localizing films into foreign languages, international voice actors can record driving videos that organically reshape the character's facial performance to match the foreign phonetics and cultural gestures.
4. Enterprise Media Scaling with SyncFlo AI
In enterprise marketing and corporate communications, high-touch video content has traditionally suffered from prohibitive production costs and slow iteration cycles. Creating personalized executive briefings, interactive training avatars, and multilingual marketing campaigns frequently stalled in post-production.
At SyncFlo AI, we incorporate frontier generative creative engines like Runway Act-One into automated digital asset pipelines. By linking customer data with dynamic generative video pipelines, SyncFlo AI enables brands to produce bespoke, high-converting video assets, customized product explainers, and localized marketing narratives at unprecedented velocity—slashing production overhead while preserving emotional authenticity.