Meta FAIR Unveils Spirit LM: First Open-Source Interleaved Speech-and-Text Foundation Model Unifying Phonetic Expression, Tone, and Linguistic Reasoning
MENLO PARK, CA — October 27, 2026 — Breaking free from the structural limitations of cascaded voice assistants, Meta Fundamental AI Research (FAIR) has publicly unveiled and open-sourced Spirit LM: the world's first open-weights multimodal foundation model capable of freely interleaving text and speech tokens within a single autoregressive neural stream.
Developed by a team of leading speech and natural language researchers at Meta FAIR—including Tu Anh Nguyen, Paul-Ambroise Duquenne, Benoit Sagot, and cognitive scientist Emmanuel Dupoux, with architectural guidance from Chief AI Scientist Yann LeCun—Spirit LM bridges the longstanding divide between written semantics and spoken human expression. The model weights, training recipes, and evaluation suites have been released under the FAIR Noncommercial Research License, giving researchers globally unprecedented access to frontier voice-native intelligence.
1. Eliminating the Cascaded Voice Bottleneck
For over a decade, conversational voice systems have relied on a fragmented, three-stage pipeline: Automatic Speech Recognition (ASR) transcribes voice into text; a Large Language Model (LLM) generates a textual reply; and a Text-to-Speech (TTS) synthesizer vocalizes the words.
This classical pipeline suffers from two catastrophic flaws:
- Emotional Amnesia: The initial ASR transcription strips away all paralinguistic nuance—such as sarcastic inflection, whispered uncertainty, excitement, vocal pitch, and hesitation—rendering the subsequent LLM blind to how words were spoken.
- Latency Serialization: Passing audio through three distinct neural engines introduces 800ms to 2,000ms of lag, destroying the natural rhythm of human conversation.
Spirit LM dissolves this paradigm by training a 7-billion-parameter transformer directly on an interleaved continuum of text BPE tokens and discrete speech tokens, enabling seamless, zero-shot multimodal generation within a single forward pass.
2. Spirit LM Base vs. Spirit LM Expressive
To balance semantic rigor with paralinguistic fidelity, Meta FAIR designed two distinct model tiers:
- Spirit LM Base: Employs discrete phonetic units derived from the self-supervised HuBERT speech representation model. The model encodes spoken phonemes into discrete tokens, allowing the core language backbone to reason simultaneously over phonetic sounds and written words with zero loss of semantic coherence.
- Spirit LM Expressive: Extends beyond phonetic units by introducing discrete pitch contours and style tokens. Spirit LM Expressive learns to model prosody, vocal timbre, emotional state, laughter, breath pauses, and intensity, allowing an AI agent to respond with empathetic tone shifts matching the speaker's emotional state.
"Human speech is vastly richer than a flat sequence of words. When we communicate, our tone, pacing, and emotional timbre convey half the meaning. Spirit LM represents the beginning of truly voice-native AI—models that listen and speak with genuine human expressiveness while maintaining deep linguistic reasoning."
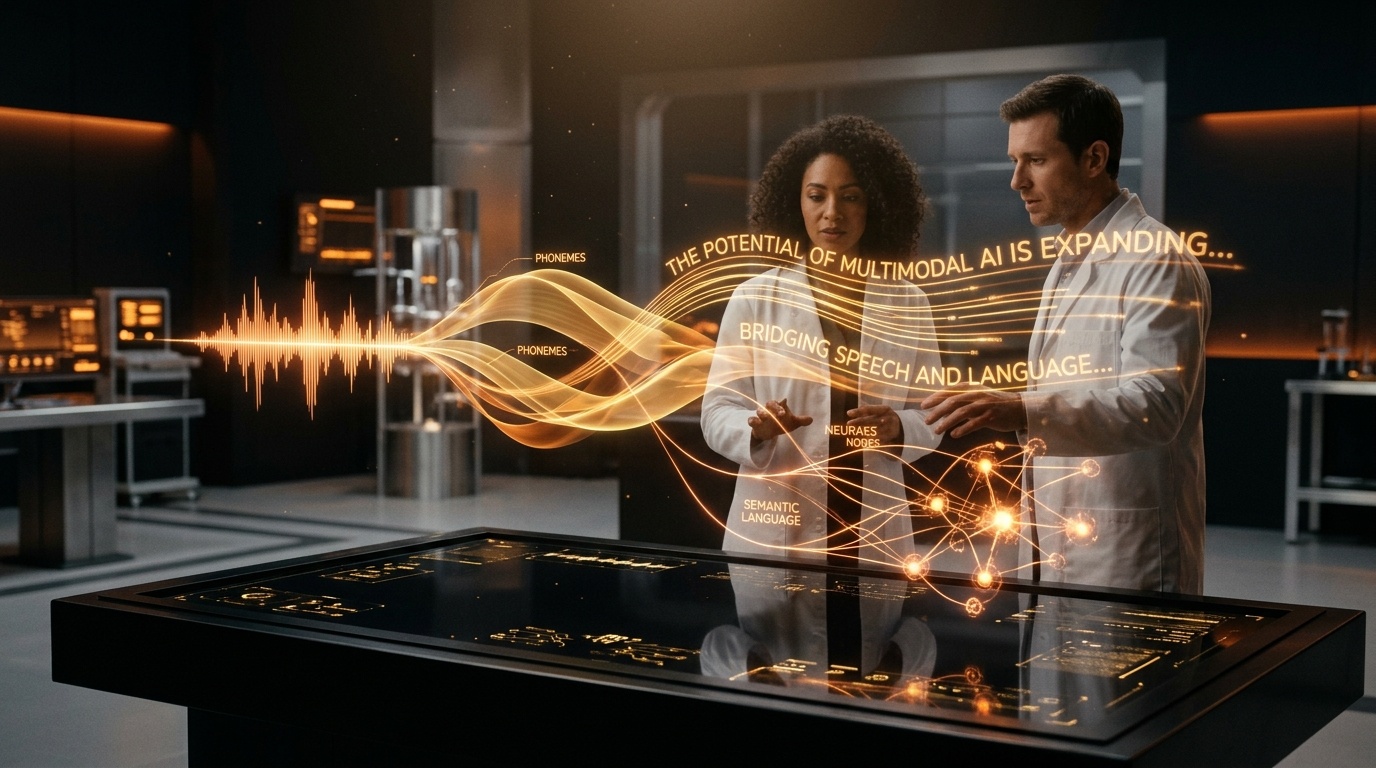
Spirit LM: Foundational Architecture & Capabilities
3. Cross-Modality Few-Shot Learning & Word-Level Interleaving
A standout capability demonstrated in Meta's benchmarks is Spirit LM's cross-modality few-shot generalization. When given a few examples of an in-context task presented exclusively in written text (e.g., sentiment analysis or formal reasoning), Spirit LM can immediately perform the task when prompted purely in spoken audio—and vice versa.
Furthermore, the model supports mid-sentence code-switching between speech and text. An agent can speak an explanation aloud, emit an interleaved programmatic code snippet in clean text, and resume vocal conversation seamlessly without ever breaking context.
4. Open Source Availability and Research Impact
By publishing Spirit LM's architecture, tokenizers, and weights on GitHub and Hugging Face, Meta has dealt a massive blow to the closed-source voice monopoly held by proprietary streaming APIs. Academic laboratories and open-source developers can now study phonetic representation alignment, emotional prosody transfer, and speech safety guardrails without incurring astronomical cloud fees.
5. SyncFlo AI Synthesis: Powering Ambient Voice Intelligence
For enterprise workflows and customer operations, Spirit LM heralds the arrival of true conversational empathy. Customer service agents, telehealth companions, and hands-free industrial assistants can now pick up on subtle vocal indicators—such as customer frustration, urgency, or hesitation—and respond with context-appropriate tone and reassurance.
At SyncFlo AI, our intelligent enterprise platform bridges frontier models like Spirit LM directly into mission-critical workflows. By combining Meta FAIR's expressive spoken intelligence with SyncFlo AI's real-time orchestration pipelines, businesses can deploy voice-first autonomous agents capable of conducting fluid, empathetic, and latency-free phone calls, voice memos, and multimodal collaboration across enterprise tools.