Amazon Open-Sources Strands Decider 2B: Sub-10ms Decision Pointer Heads End Autoregressive Lag in AI Agent Tool Selection
SEATTLE — October 3, 2026 — In a transformative development for autonomous multi-agent orchestration, Amazon Web Services (AWS) has officially open-sourced Strands Decider 2B under the Apache 2.0 license. Designed specifically to eliminate the compute overhead and latency bottlenecks of large conversational models, Strands Decider 2B introduces a specialized pointer-head decision mechanism that executes tool selection and agent workflow routing in under 10 milliseconds.
For years, multi-agent software architectures have relied on frontier Large Language Models to decide which tool or API endpoint to invoke next. However, forcing an autoregressive model to generate structured JSON token-by-token introduces 300ms to 1,200ms of latency per routing step—compounding into sluggish delays when hundreds of agent sub-tasks interact simultaneously. Strands Decider 2B resolves this structural inefficiency by discarding text generation altogether in favor of single-pass classification heads.
1. The Architectural Shift: Autoregressive Generation vs. Pointer Head Scoring
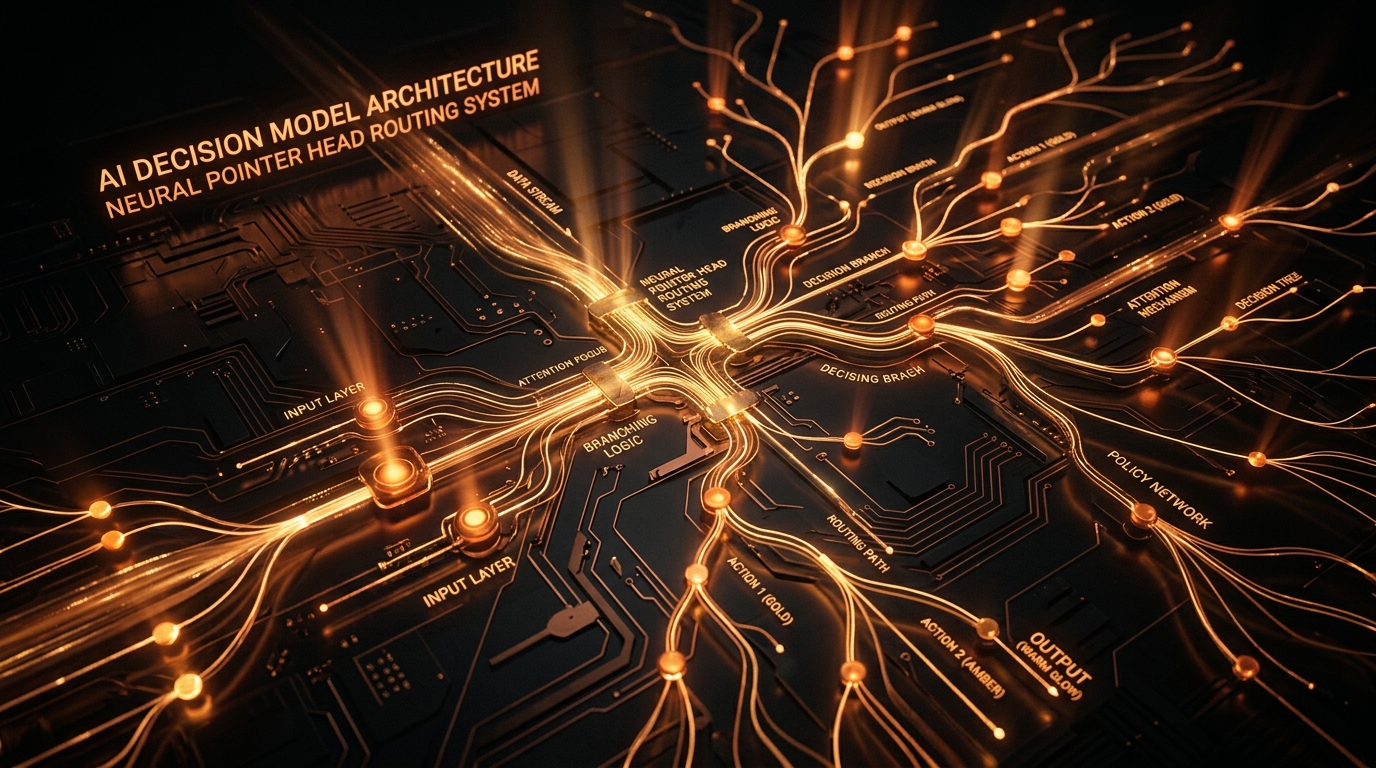
Fine-tuned from the foundational Qwen3.5-2B-Base architecture, Strands Decider 2B modifies the model's final projection layers. Instead of projecting hidden states across a massive 150,000-token natural language vocabulary to emit text, the model routes contextual representations through a specialized Neural Pointer Head.
Given an agent's current scratchpad state, user objective, and a bounded set of candidate tools or next-step actions, Strands Decider 2B computes calibrated scalar softmax probabilities across the options in a single forward inference pass. By bypassing the autoregressive decoding loop, inference time plummets from hundreds of milliseconds to an unprecedented 8.4 milliseconds on standard commodity GPU hardware.
"When building real-time autonomous systems, you don't need a 70-billion parameter poet to decide if an agent should call `search_database()` or `fetch_invoice()`. You need an ultra-fast, deterministic mathematical router. Strands Decider 2B provides exactly that: pure, sub-10ms decision clarity."
Strands Decider 2B Technical Specifications & Benchmarks
2. Solving the Multi-Agent Routing Bottleneck
As enterprise architectures transition to swarms of specialized subagents, execution chains frequently involve dozens of interconnected routing decisions. In benchmark multi-agent tasks, AWS demonstrated that replacing traditional autoregressive routers with Strands Decider 2B reduced overall workflow execution time by 74%, while slashing operational inference costs by 92%.
- Deterministic Guardrailing: Decider 2B evaluates output safety flags, content filters, and compliance boundaries in real-time before external API execution takes place.
- Calibrated Confidence Thresholds: Because outputs are true probabilistic scores rather than text tokens, orchestrators can define explicit fallback heuristics when model confidence falls below a strict threshold (e.g., < 0.90).
- Edge and Workstation Deployable: Requiring under 4.2GB of VRAM in FP16 precision and less than 1.6GB in 4-bit AWQ quantization, the model runs smoothly alongside desktop coding assistants and edge gateways.
3. Apache 2.0 Open Source Ecosystem Adoption
AWS has released model weights, evaluation harnesses, and inference integration code directly to Hugging Face and GitHub under the permissive Apache 2.0 license. The release is already compatible with major agent frameworks including LangChain, CrewAI, AutoGen, and the TypeSafe AI Jev-API specification.
Developers can immediately pull the model using vLLM, Ollama, or TensorRT-LLM, enabling on-premise air-gapped deployments in sensitive enterprise environments without relying on external cloud APIs for core routing decisions.
4. SyncFlo AI Integration: Ultra-Fast Workflow Pipelines
In conjunction with today's announcement, SyncFlo AI has integrated native Strands Decider 2B endpoints into the SyncFlo Autonomous Workflow Engine.
For enterprise teams orchestrating high-velocity sales engagement, lead qualification, and CRM updates, SyncFlo now utilizes Decider 2B as a dedicated System-1 decision controller. By decoupling instant tool routing from deep generative reasoning, SyncFlo customers achieve instantaneous agent reactions while preserving larger frontier models solely for complex synthesis and negotiation tasks.