NVIDIA Launches RTX Spark: Blackwell Superchip Brings 1 PFLOPS Local AI Agent Processing to Windows PCs
SANTA CLARA, CA — October 1, 2026 — In what marks a milestone in edge computing, NVIDIA today announced the commercial launch of NVIDIA RTX Spark, a groundbreaking desktop superchip platform engineered to shift generative reasoning and autonomous agent workloads from remote cloud datacenters directly into personal Windows workstations.
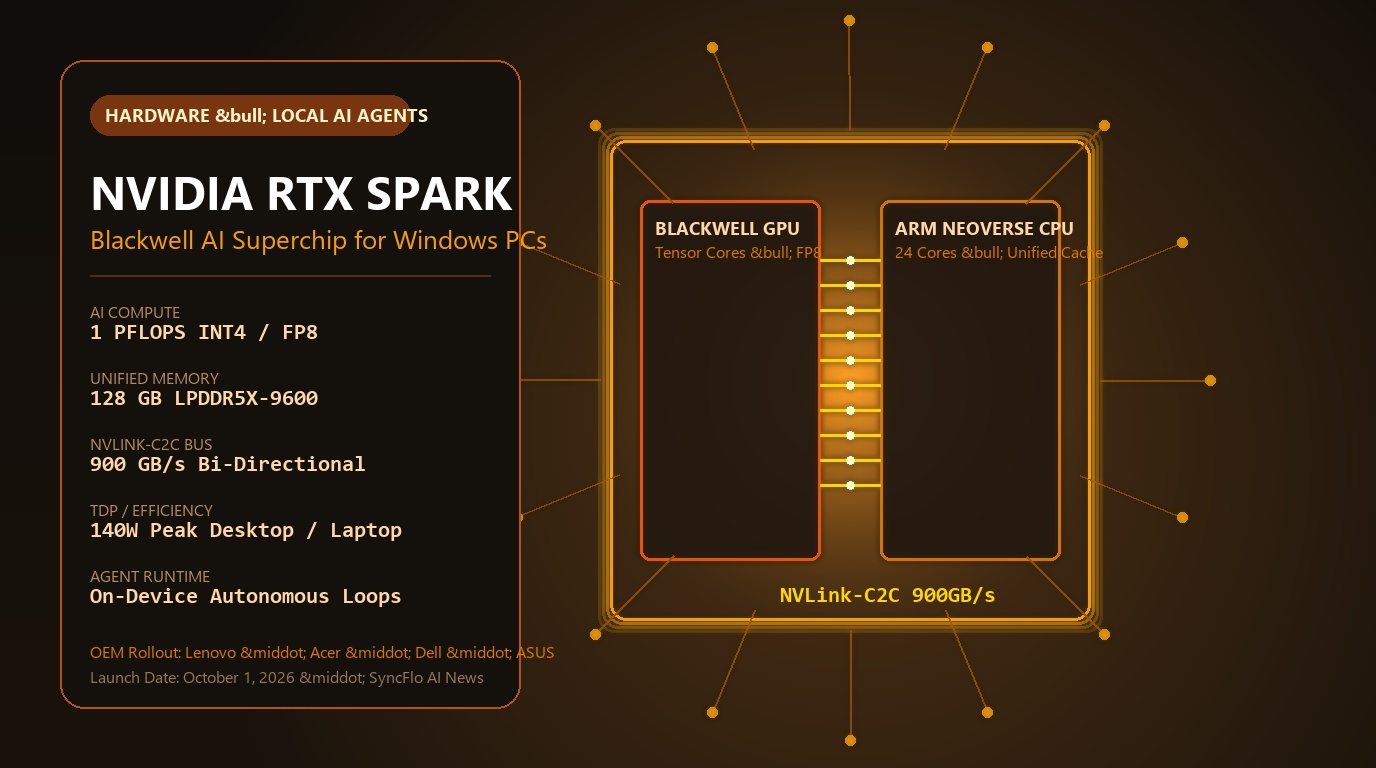
By coupling an energy-efficient 24-core Arm Neoverse CPU directly to a high-density Blackwell-generation GPU through a coherent 900 GB/s NVLink-C2C interconnect, RTX Spark provides up to 1 PFLOPS of INT4/FP8 AI compute and up to 128GB of ultra-fast unified LPDDR5X memory inside a compact 140-watt thermal envelope. The release is accompanied by immediate production shipments from tier-one hardware manufacturers including Lenovo, Acer, ASUS, and Dell.
1. Decoupling AI from the Cloud: Privacy, Latency, and Economics
As enterprise workflows transition toward persistent, multi-step autonomous AI agents, cloud API costs and latency bottlenecks have grown into major adoption hurdles. Sending millions of keystrokes, DOM clicks, database queries, and private source trees to cloud endpoints introduces compounding latency and sensitive data governance risks.
RTX Spark addresses this challenge by running multi-modal reasoning models—such as 70-billion-parameter MoE models, on-device vision agents, and terminal coders—locally at lightning speed. By eliminating the network round-trip, agentic loops that previously required several seconds over web sockets execute in single-digit milliseconds directly on the workstation motherboard.
"Every software developer, financial analyst, and creative professional should have their own personal supercomputer sitting silently under their desk. With RTX Spark, we have crammed a datacenter's worth of Blackwell AI muscle and coherent memory into a desktop PC that runs local agent swarms with zero latency and complete privacy."
NVIDIA RTX Spark Technical Specifications
2. Silicon Architecture: NVLink-C2C and Coherent Memory
The core breakthrough of RTX Spark lies in its memory architecture. Traditional discrete PC GPUs are bottlenecked by PCIe bus transfer speeds when passing large multimodal contexts between host system RAM and GPU VRAM. RTX Spark solves this by placing the CPU and GPU dies on a single high-density interposer connected by NVIDIA's proprietary NVLink-C2C (Chip-to-Chip) interface.
Because the Arm CPU and Blackwell GPU share a unified address space, local agent software can feed large enterprise datasets, PDFs, and video streams directly into Tensor Core pipelines without duplicating memory buffers or waiting for PCIe bus serialization.
3. OEM Hardware Rollout & Ecosystem Support
Hardware partners are rolling out workstations and compact form-factor systems throughout October 2026:
- Lenovo ThinkStation Spark: Enterprise-certified workstation engineered for defense, healthcare, and financial compliance with hardware-isolated biometric key stores.
- Acer Predator Triton Spark: High-performance mobile workstation for creators and engineers on the go.
- Dell Precision 7000 Series Spark Edition: Rackable and tower configurations optimized for engineering simulations and autonomous local software development.
- ASUS ProArt Studio Spark: Minimalist silent-chassis desktop designed specifically for AI-assisted digital film production and 3D architectural rendering.
4. SyncFlo AI Integration: Local-First Enterprise Agent Workspaces
As organizations adopt on-device computing to protect intellectual property and streamline operational expenditure, SyncFlo AI has launched native support for the RTX Spark runtime.
With SyncFlo's hybrid deployment topology, enterprise revenue teams can run sensitive customer qualification, pipeline auditing, and automated outreach agents locally on RTX Spark workstations—only syncing cryptographically verified results with their cloud CRM when human approvals are granted. This delivers maximum data sovereignty without compromising pipeline automation speed.