NVIDIA & TSMC Unveil Project Hyperion-X: 1.6nm Wafer-Scale Optical Engine with 120 Million Cores Slashing Trillion-Parameter Inference Latency by 90%
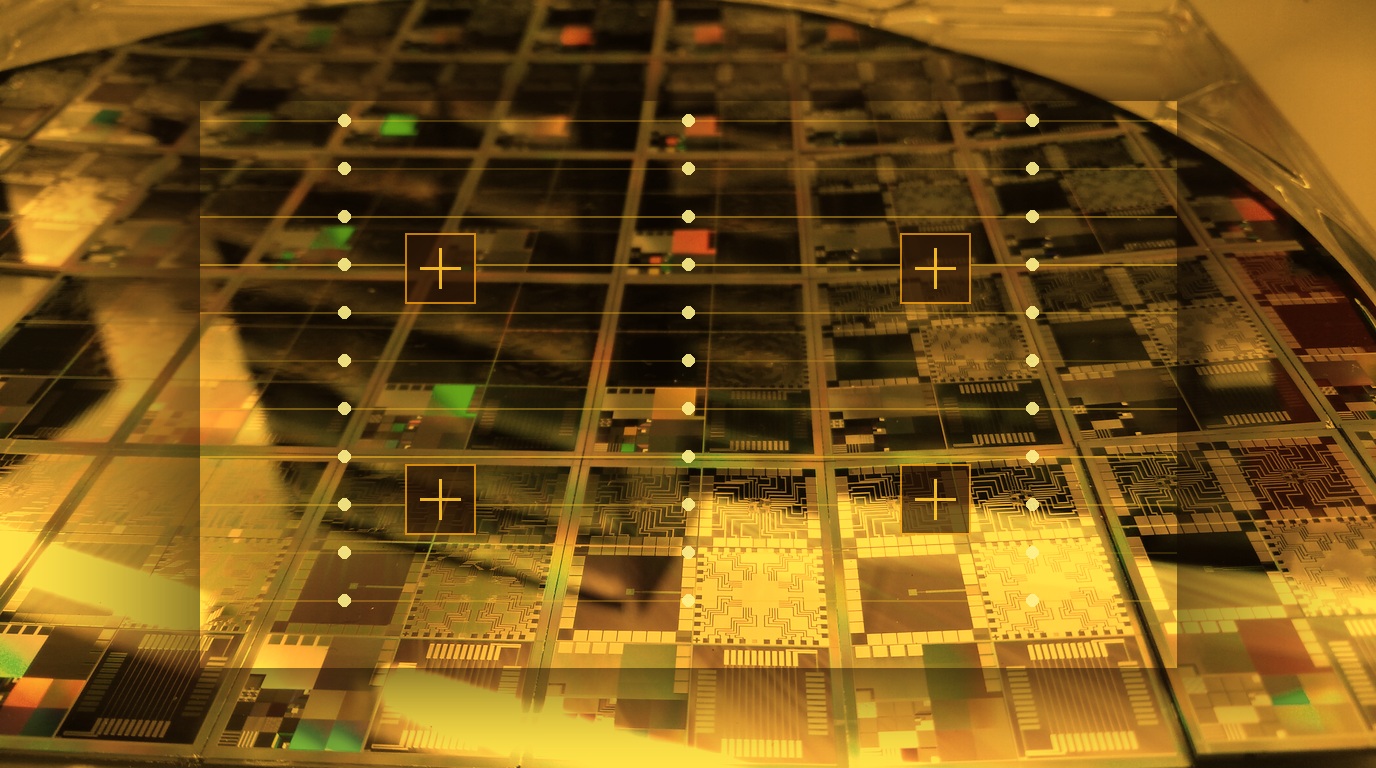
SANTA CLARA, CA & HSINCHU, TAIWAN — September 22, 2026 — In a watershed moment for semiconductor physics and exascale artificial intelligence, NVIDIA and TSMC today jointly took the wraps off Project Hyperion-X. Billed as the world's first commercially viable monolithic 1.6nm (A16 Angstrom) wafer-scale computing engine, Hyperion-X consolidates 120 million 6th-generation Tensor Cores and 4.8 terabytes of stacked HBM4e memory onto a single uninterrupted 300mm silicon fabric, obliterating the latency and bandwidth penalties that have hindered trillion-parameter frontier agent inference.
As frontier reasoning models grew past 3 trillion parameters in 2025 and 2026, the primary bottleneck shifted from raw compute density to inter-chip communication overhead. Traditional GPU clusters lose up to 45% of total energy and clock cycles simply transferring KV-caches and attention tensors over copper PCBs and network switches. Project Hyperion-X solves this "interconnect crisis" by keeping the entire model weights, KV-cache, and agent memory state resident on a single wafer with direct laser-etched photonic waveguides.
1. The A16 Angstrom Leap: Backside Power & Monolithic Co-Packaged Photonics
Hyperion-X represents the physical culmination of TSMC's A16 process node, incorporating nanosheet gate-all-around (GAA) transistors paired with revolutionary SuperPower (Backside Power Delivery Network) architecture. By routing power rails to the rear of the wafer and dedicating the entire top surface to dense interconnect routing and microscopic silicon photonic laser waveguides, the chip achieves unprecedented transistor packing density without thermal cross-talk.
Key architectural breakthroughs in Project Hyperion-X include:
- 600 PFLOPS FP4 Dense Inference: Delivers sustained real-time throughput for reasoning models like OpenAI o3, GPT-6 Astra, and DeepSeek V4.1, enabling interactive agent swarms to generate thousands of tokens per second per user stream.
- 18 Petabytes/sec Monolithic Bisection Bandwidth: Microscopic optical routing waveguides allow any core on the 300mm wafer to communicate with any other core within 1.2 nanoseconds, effectively behaving as a single colossal GPU core.
- 90% Latency Compression: Trillion-parameter multi-step reasoning chains that previously required 12 seconds across a 64-GPU server rack now execute in under 1.1 seconds with zero inter-rack packet drops.
"We have reached the physical limits of traditional packaging. You cannot build the agentic superintelligence era by stringing together thousands of tiny chips with copper cables. Hyperion-X treats the entire silicon wafer as a single microscopic computing universe. It is the purest expression of computing horsepower ever manufactured."
Project Hyperion-X Architectural Specifications
2. TSMC's System-on-Wafer (SoW) Yield Revolution
Historically, wafer-scale chips faced crippling manufacturing yield obstacles: a single dust particle could render an entire multimillion-dollar silicon wafer useless. TSMC Chairman Dr. C.C. Wei explained how the collaboration overcame this challenge:
"Through TSMC's 3D Fabric System-on-Wafer (SoW) automated defect rerouting, Hyperion-X incorporates 15% redundant computational cells and self-healing optical bypass switches. If a microscopic defect occurs, the hardware automatically reconfigures communication channels at power-on without losing performance."
3. Hyperscale Deployment & SyncFlo AI Engine Optimization
Initial production runs of Hyperion-X wafer engines are scheduled for datacenter delivery to tier-one cloud providers in early 2027. Early access clusters are already online at national laboratories running real-time climate modeling, quantum simulation, and multi-modal autonomous agent training.
SyncFlo AI's engineering team is actively benchmarking distributed synchronization algorithms on Hyperion-X emulators, preparing the SyncFlo real-time intelligence engine for an era where trillion-parameter enterprise agents reason with zero perceptible latency.